Thumbnail system v4 · results page · built 2026-11-05
Thumbnail generation methods: what we tested and what won
Main test Nov 4 on your 12 latest videos: 619 renders, 19 recipes, every render scored blind by two AI judges plus code checks (face match, brightness, stray text). Later tests at the bottom.
The short answer
- Winner ("WIN"): GPT Image 2.5 through Magnific, with 3 photos of you, the character sheet, 1-2 real photos of the object, one clean round-5 render as a style reference, and the long round-5 prompt. The prompt places everything, no layout aids.
- In a follow-up on 85 new ideas it beat the round-5 recipe on 55 (lost 28, 2 ties).
- The model matters most. Nano Banana and Seedream scored over a judge point lower and lost your face on most renders (4-33% pass the face floor vs 73% for GPT).
- Layout aids made it worse: an outlier thumbnail as the base, an AI clay plan, a Blender 3D plan.
- Short prompts made it worse. A fancier director-style prompt was no better.
Read this with one caveat
AI judges did the scoring. They agreed with your past picks about 65% of the time, and on the 123 finals you reviewed afterwards their score predicted your keep or drop no better than a coin flip. So "won" here means "the judges liked it more". The big gaps (model, layout aids) are large enough to trust; the small ones are not. Your own blind picks (Later tests) are the stronger evidence where they exist.
Every method, on the same 4 ideas
Each method changes one thing from the round-5 recipe, on up to 24 ideas (Seedream 12, AI clay plan 19, Blender 3D plan 9; "Everything" changes several things at once). The number is the change in the judges' score versus round 5, in judge points out of 10, with the 90% range in brackets; one render per idea, so anything under about 0.2 points is noise. Face match = share of renders that pass the 0.72 likeness floor.
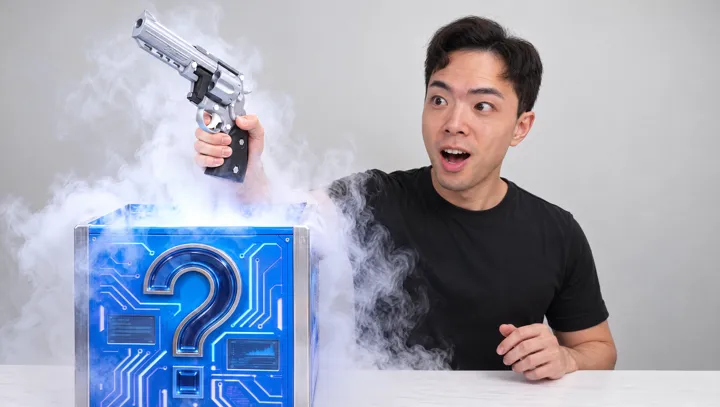
I Tested Every Satisfying 3D Print
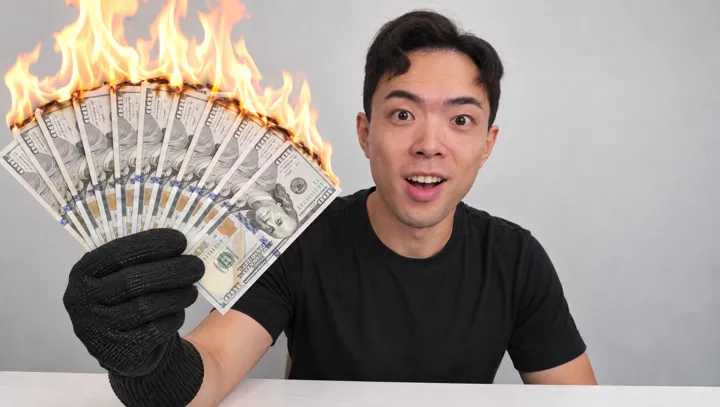
Experiments That Look FAKE But Are Actually REAL!
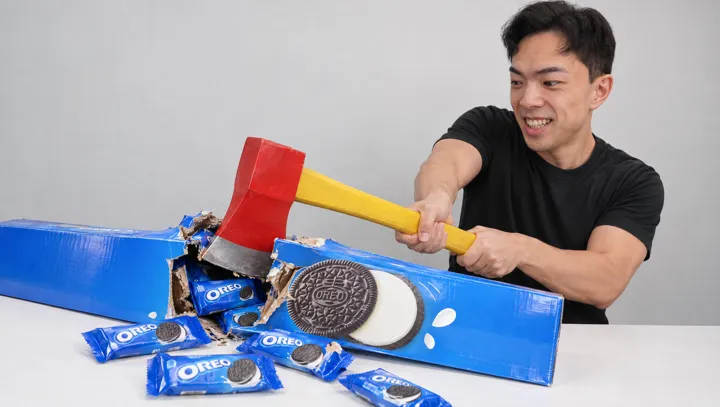
I Bought the World's Biggest Snacks!
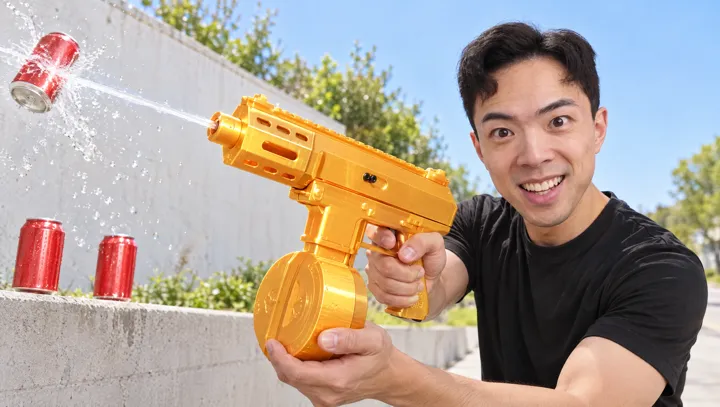
Level 1 to 100 3D Prints
BaselineRound-5 recipe (the one you called best so far)
Face match 73% · GPT Image 2.5, 1 face photo + object photos + body panel, the long prompt.
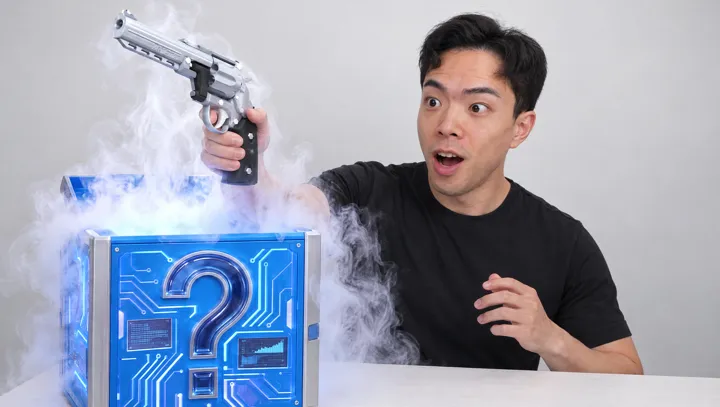
judges 6.9/10 · face 0.80
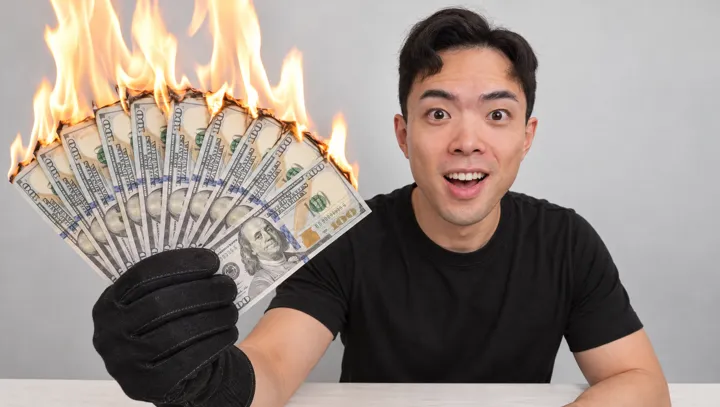
judges 6.6/10 · face 0.81
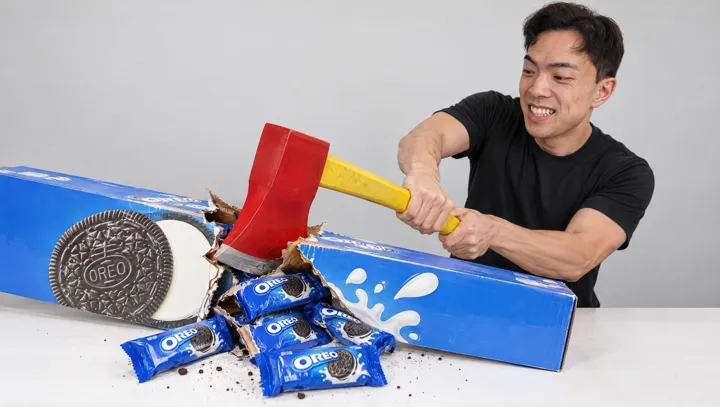
judges 6.5/10 · face 0.74
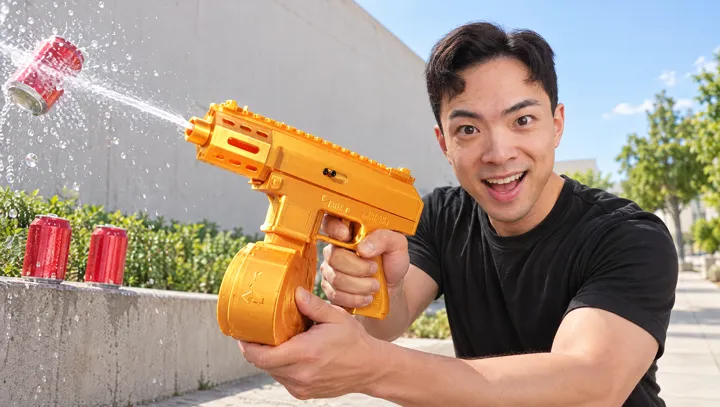
judges 6.6/10 · face 0.80
WorseNano Banana 2.1 instead of GPT
-1.2 points (-1.3 to -1.0) · face match 4% · Lost your face on almost every render.
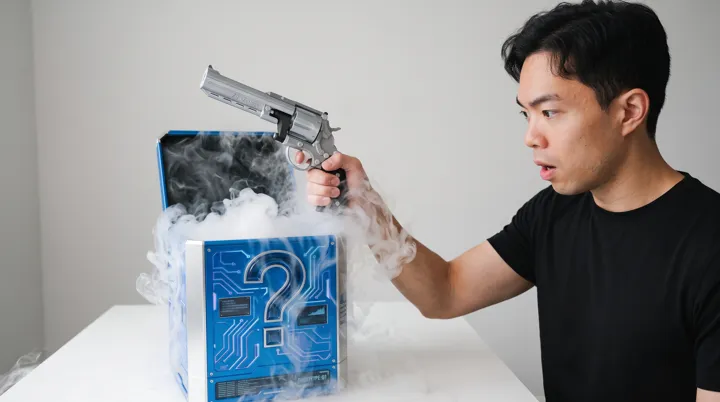
judges 4.2/10 · face 0.62 · a judge rejected it
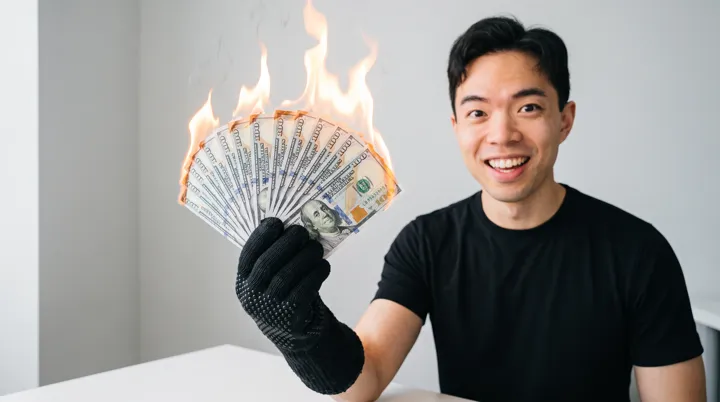
judges 6.1/10 · face 0.64
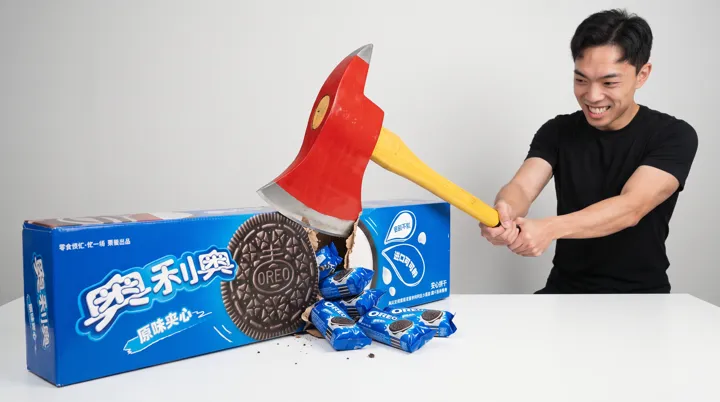
judges 4.8/10 · face 0.66 · a judge rejected it
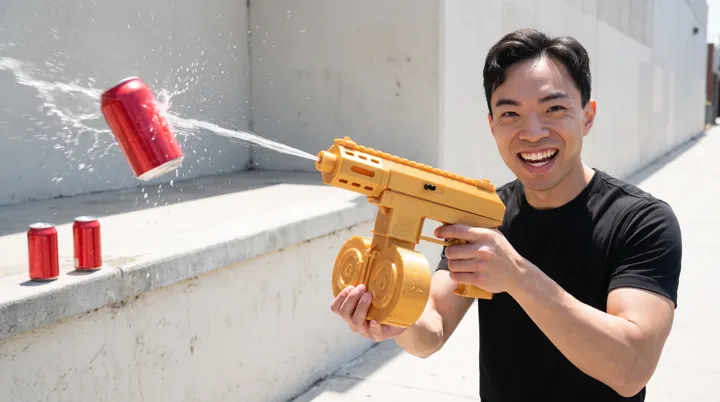
judges 5.9/10 · face 0.62
WorseNano Banana Pro instead of GPT
-1.3 points (-1.4 to -1.1) · face match 4%
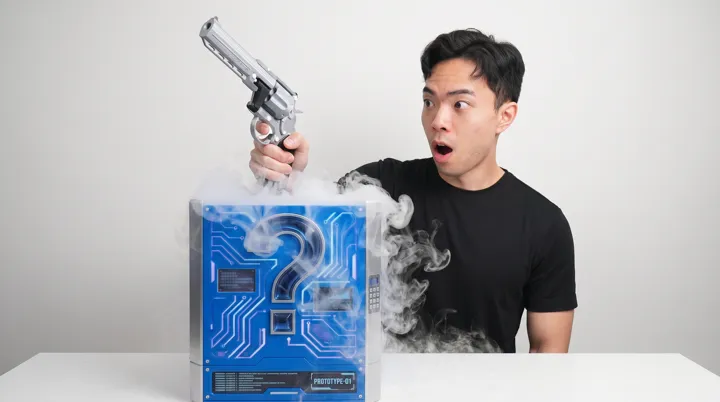
judges 4.9/10 · face 0.68
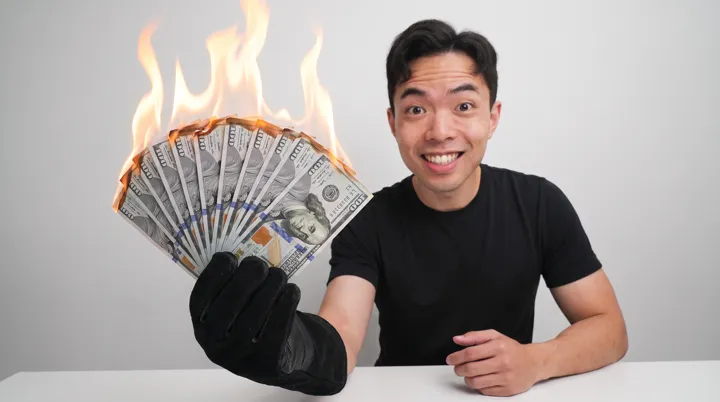
judges 6.0/10 · face 0.70
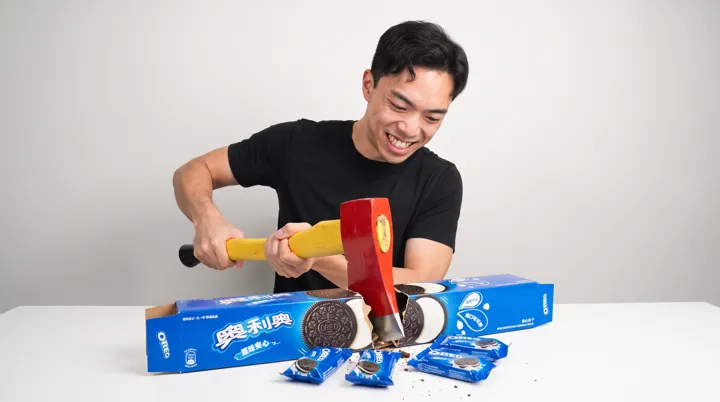
judges 4.0/10 · face 0.60 · a judge rejected it
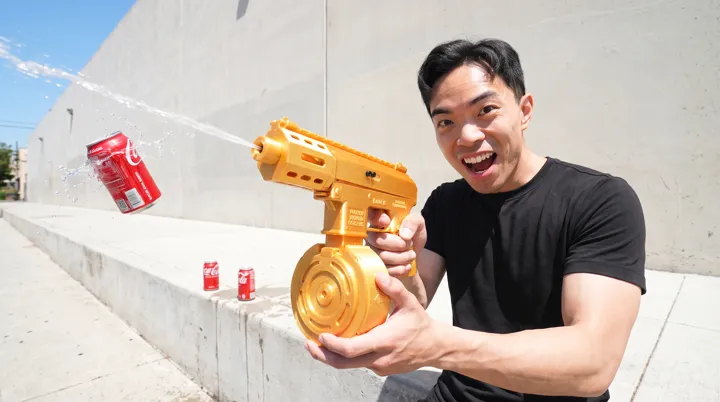
judges 4.8/10 · face 0.61
WorseSeedream 5.0 Pro instead of GPT
-1.4 points (-1.7 to -1.1) · face match 33% · Got the GPT-tuned prompt, nothing written for it.
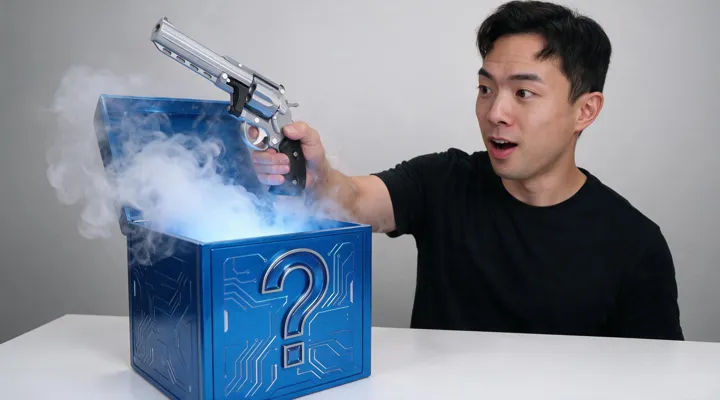
judges 6.5/10 · face 0.70
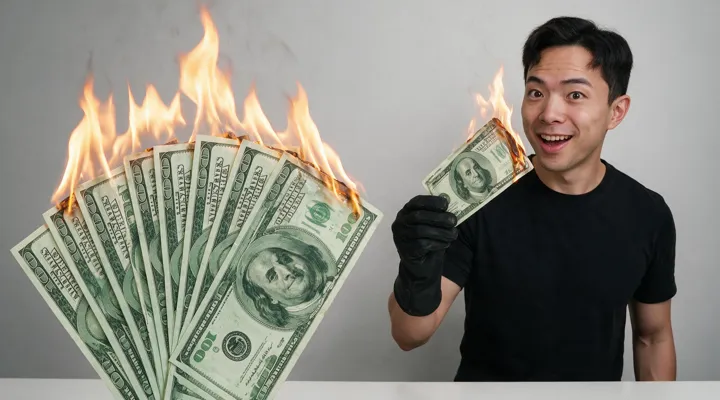
judges 3.6/10 · face 0.77 · a judge rejected it
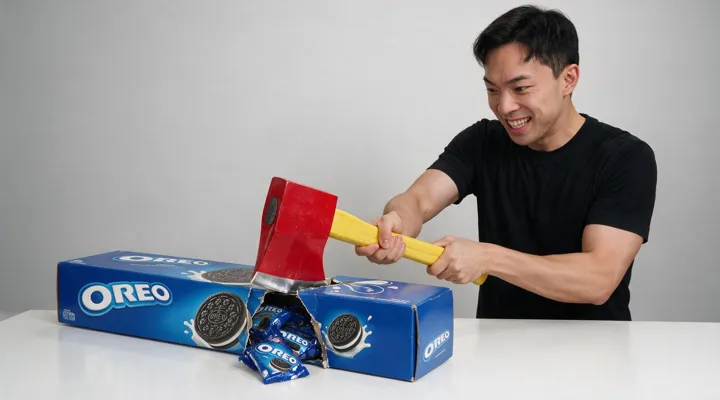
judges 4.9/10 · face 0.71 · a judge rejected it
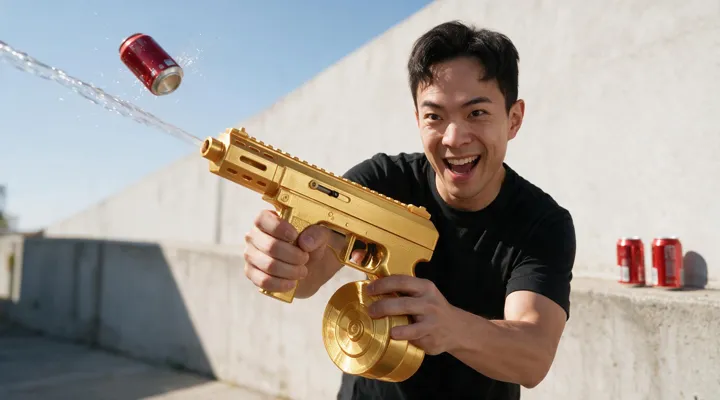
judges 4.6/10 · face 0.64 · a judge rejected it
WorseAn outlier thumbnail as the base image, edited (Marcus style)
-0.4 points (-0.7 to -0.2) · face match 64%
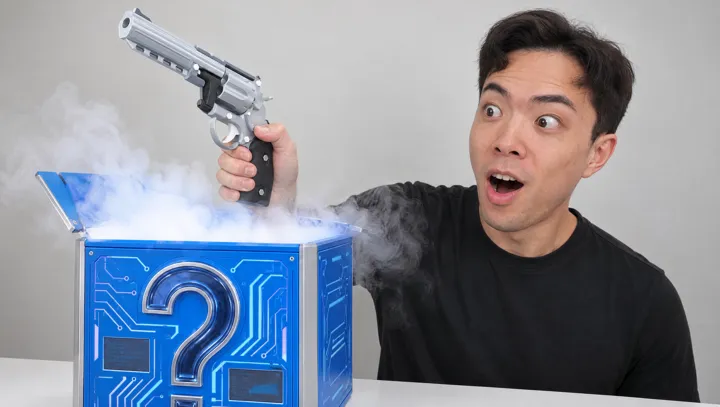
judges 6.8/10 · face 0.76
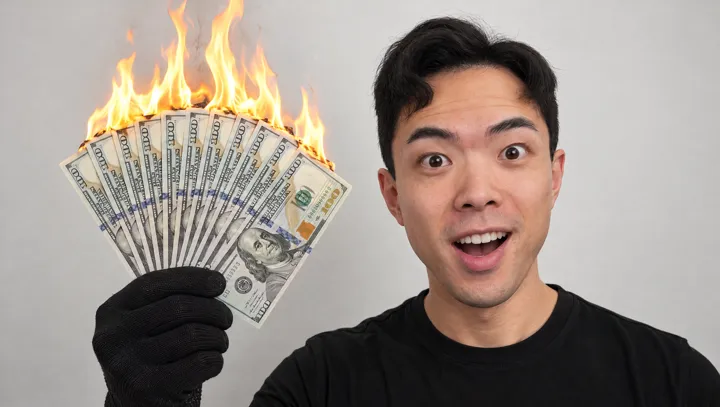
judges 6.4/10 · face 0.81
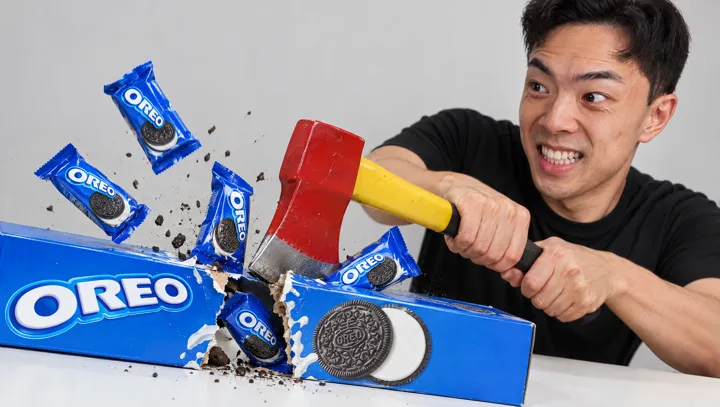
judges 7.5/10 · face 0.73
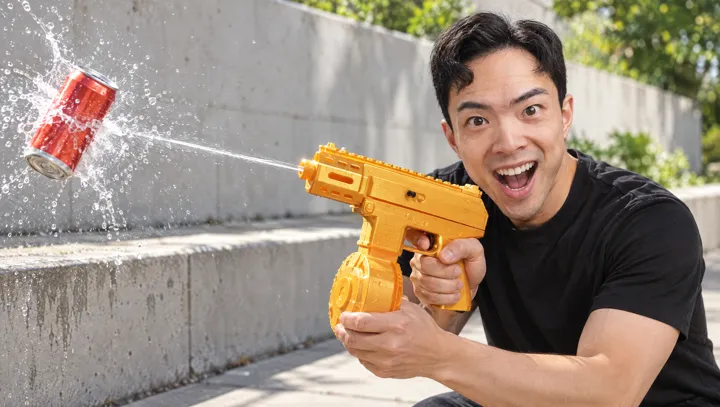
judges 6.0/10 · face 0.77
WorseAI gray clay plan first, then render from it
-0.8 points (-1.0 to -0.6) · face match 53%
judges 5.2/10 · face 0.71
judges 6.0/10 · face 0.82
judges 4.4/10 · face 0.68
judges 5.5/10 · face 0.76
WorseBlender 3D gray plan first (old body model)
-0.5 points (-0.7 to -0.2) · face match 78% · Only 9 ideas. The newer 3D plan was re-tested later (see Later tests).
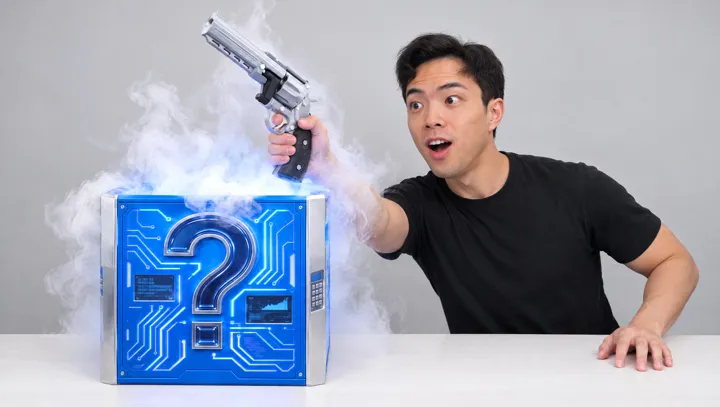
judges 6.1/10 · face 0.77
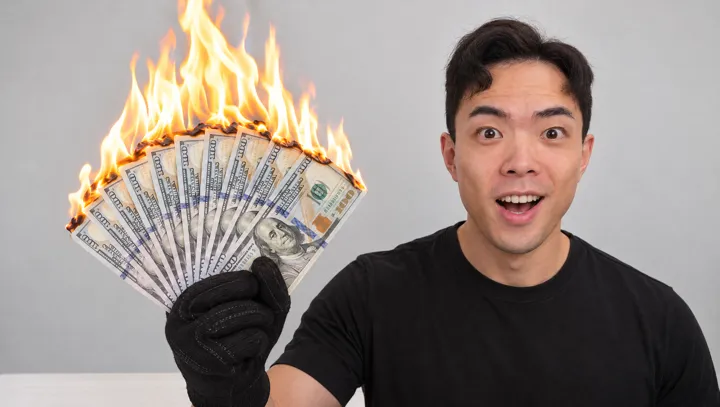
judges 6.1/10 · face 0.82
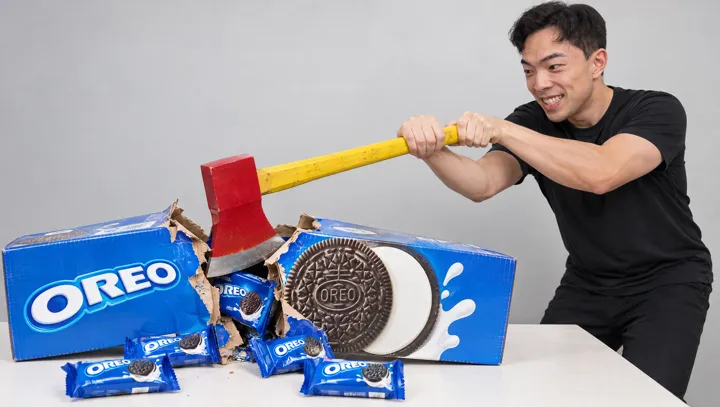
judges 6.4/10 · face 0.70
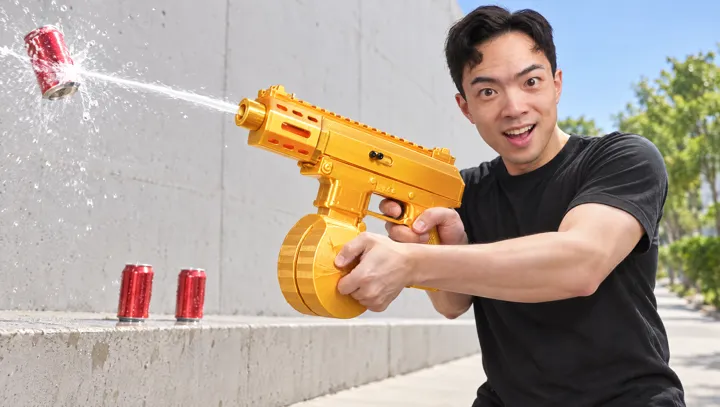
judges 6.2/10 · face 0.79
WorseShort prompt (70 words)
-0.4 points (-0.6 to -0.1) · face match 77%
judges 6.0/10 · face 0.78
judges 6.9/10 · face 0.84
judges 6.5/10 · face 0.68
judges 5.2/10 · face 0.81
No clear differenceDirector-style prompt (camera, grid, first and second read, avoid list)
+0.1 points (-0.1 to +0.3) · face match 75%
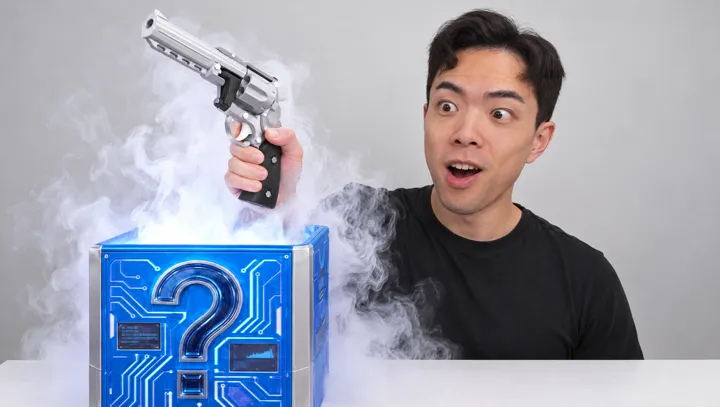
judges 6.9/10 · face 0.81
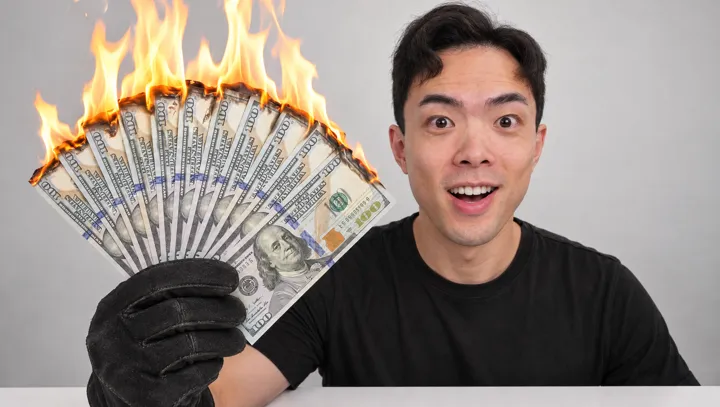
judges 6.8/10 · face 0.82
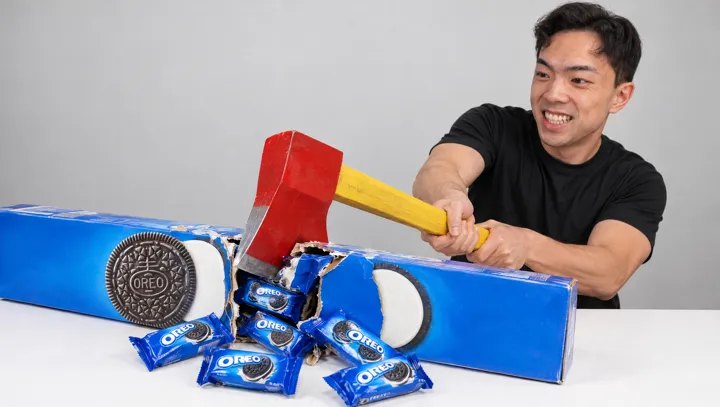
judges 6.2/10 · face 0.79
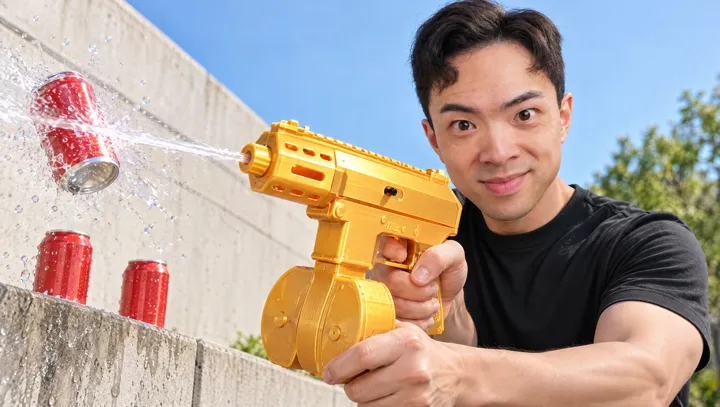
judges 6/10 · face 0.82
No clear differenceFace photo only, no object or body pictures
+0.0 points (-0.2 to +0.2) · face match 91%
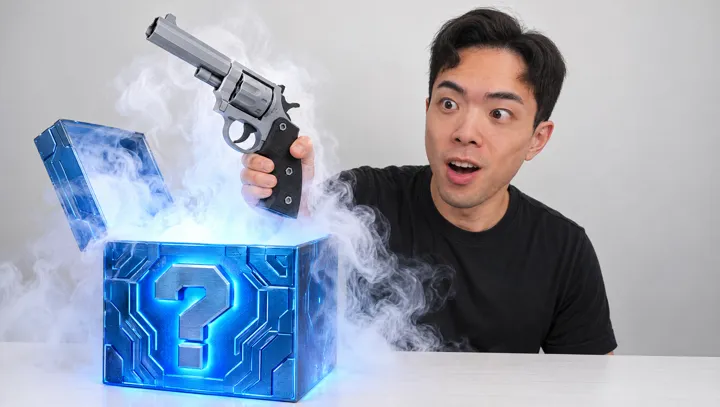
judges 7.1/10 · face 0.83
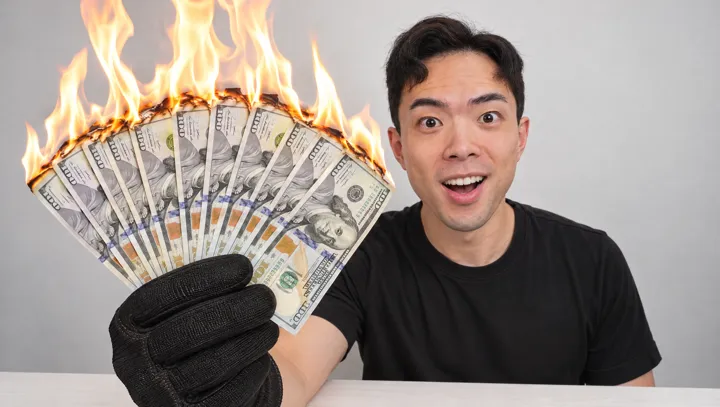
judges 6.8/10 · face 0.85
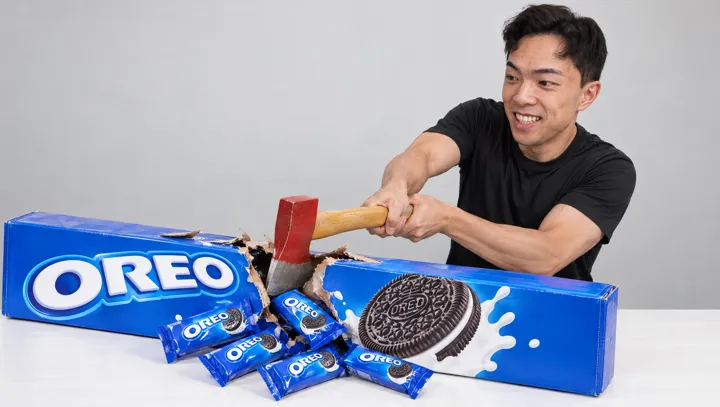
judges 5.8/10 · face 0.75
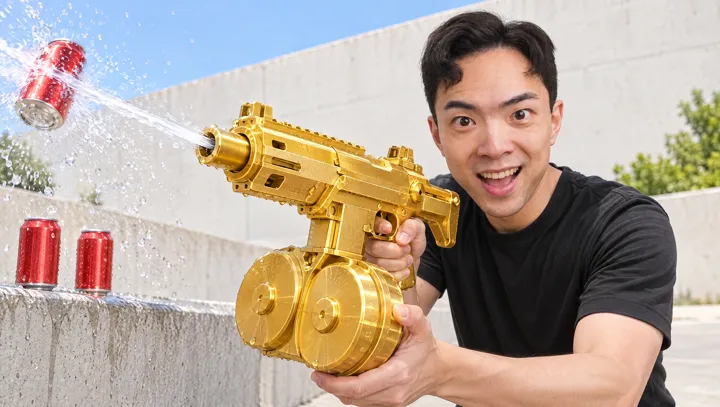
judges 6.4/10 · face 0.79
No clear difference3 face photos instead of 1
+0.0 points (-0.1 to +0.2) · face match 91%
judges 7.0/10 · face 0.80
judges 6.4/10 · face 0.85
judges 6.0/10 · face 0.76
judges 6.8/10 · face 0.76
Small plusCharacter sheet instead of the body panel
+0.2 points (+0.0 to +0.3) · face match 83% · Weak.
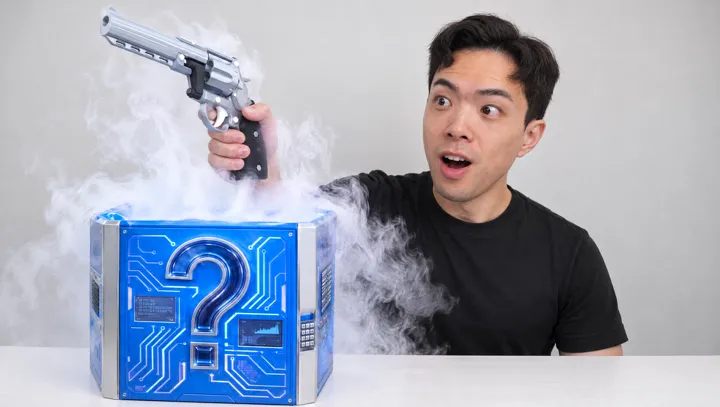
judges 7.1/10 · face 0.82
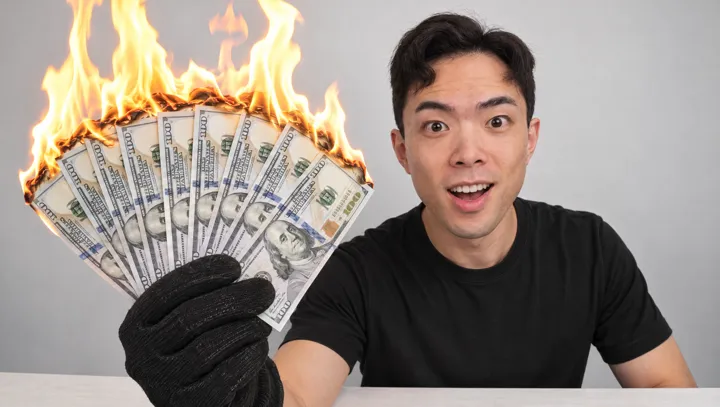
judges 6.8/10 · face 0.85
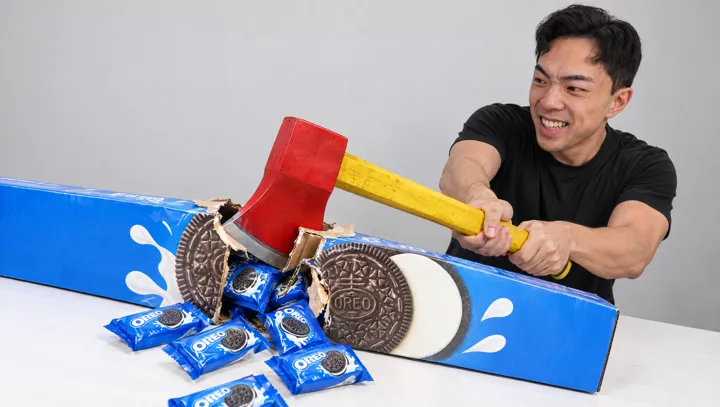
judges 6.6/10 · face 0.74
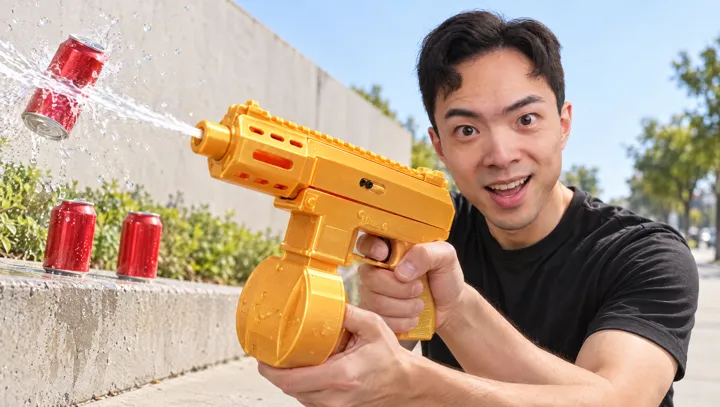
judges 6.2/10 · face 0.82
Did not hold upYour fixed favorite photo instead of an emotion-matched one
+0.3 points (+0.1 to +0.4) · face match 70% · Better at first, fell to about 0 when the same images were judged again in groups of 4.
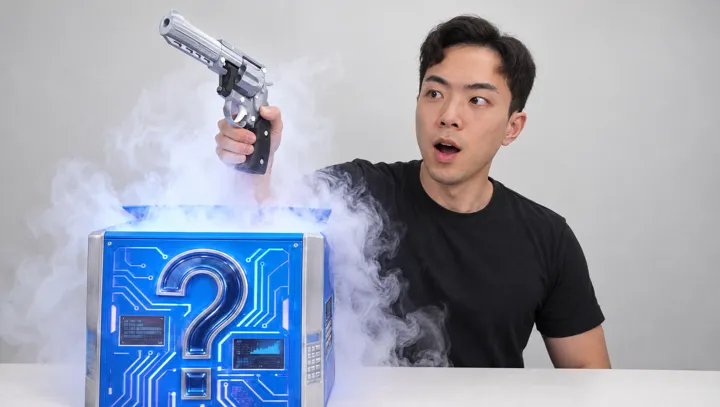
judges 7.1/10 · face 0.77
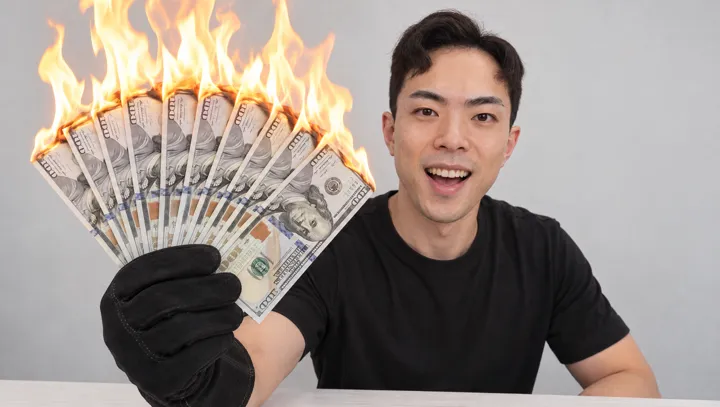
judges 7.2/10 · face 0.79
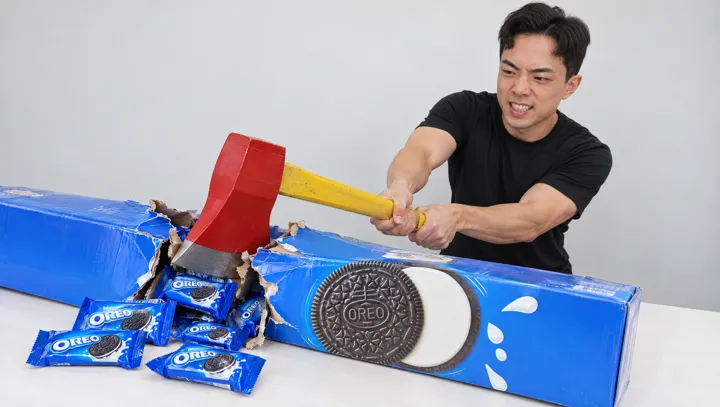
judges 6.6/10 · face 0.67
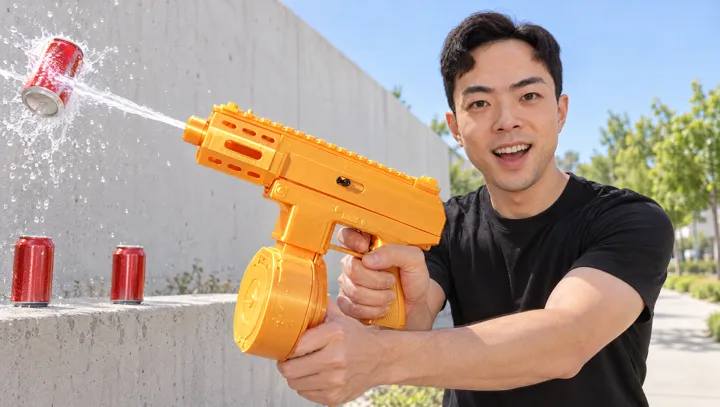
judges 6.9/10 · face 0.73
No clear differenceA style reference added (one clean round-5 render)
+0.1 points (-0.1 to +0.3) · face match 87%
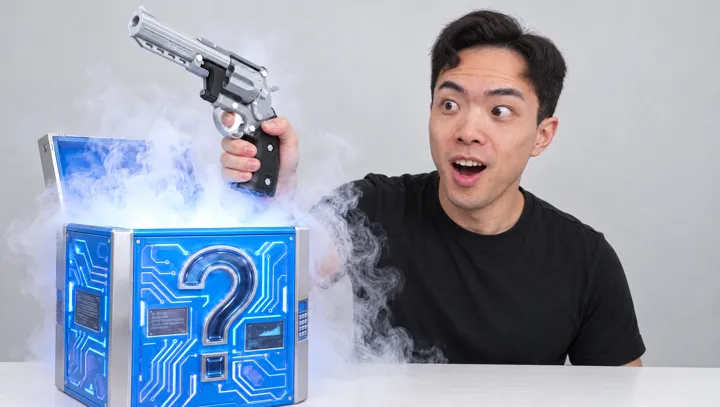
judges 6.9/10 · face 0.77
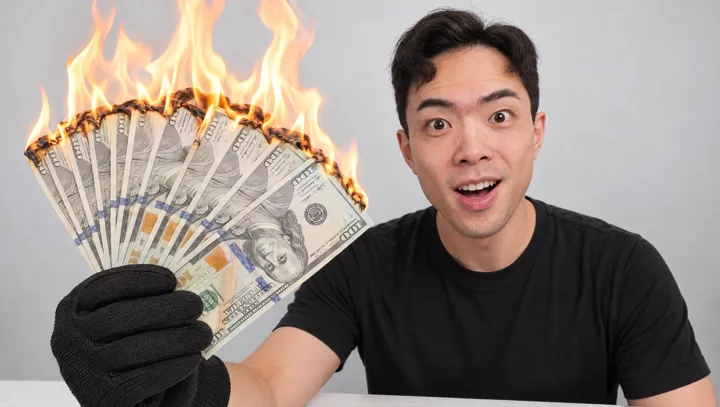
judges 6.4/10 · face 0.79
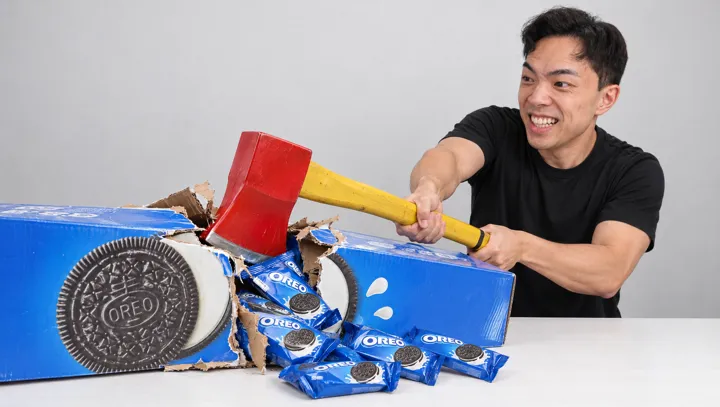
judges 6.5/10 · face 0.72
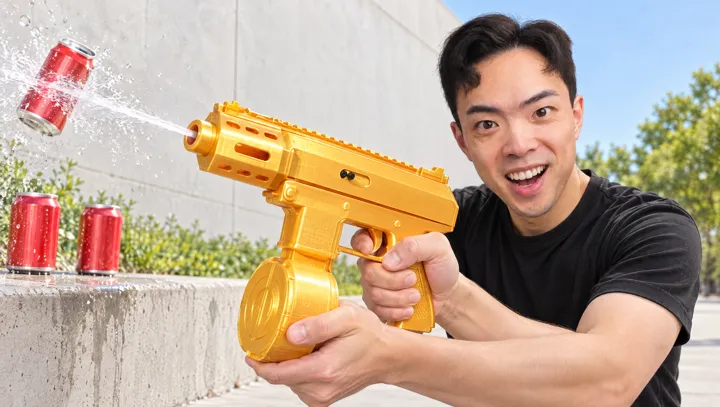
judges 6.8/10 · face 0.78
Better (kept)Everything: 3 face photos + character sheet + objects + style reference
+0.3 points (+0.1 to +0.4) · face match 87% · Changes several things at once. Held up when judged again (+0.4 points) and in a follow-up on 85 new ideas (+0.5 points). This became WIN.
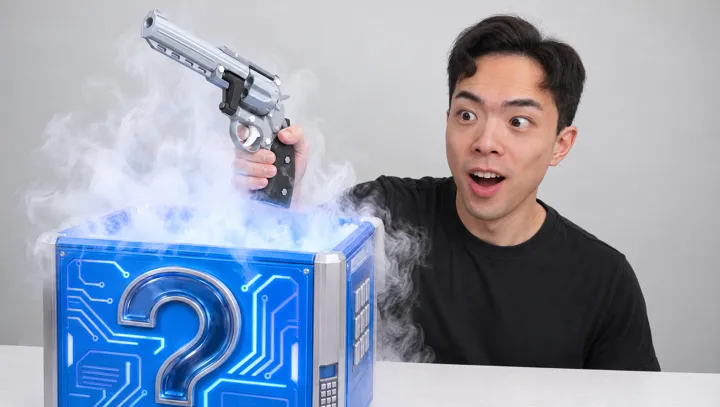
judges 6.4/10 · face 0.79
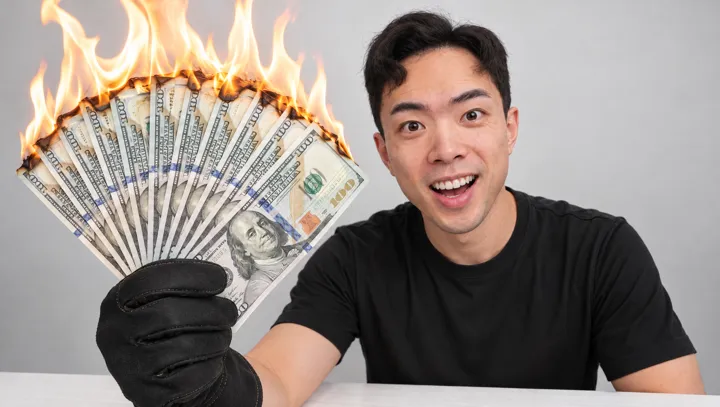
judges 7.1/10 · face 0.80
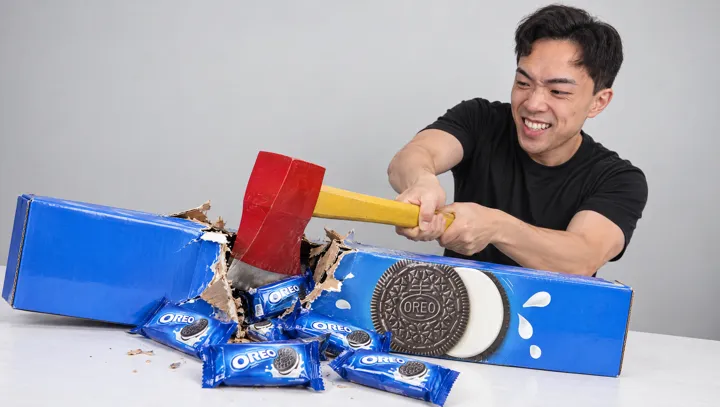
judges 6.4/10 · face 0.71
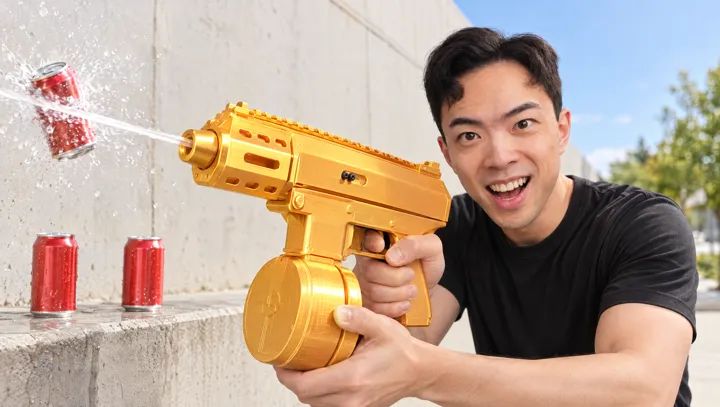
judges 6.8/10 · face 0.78
No clear differenceA hand-picked natural face photo (no stare)
+0.1 points (-0.2 to +0.4) · Judged in groups of 4, not the same scale as the rows above; +0.2 points in the 85-idea follow-up, not proven.
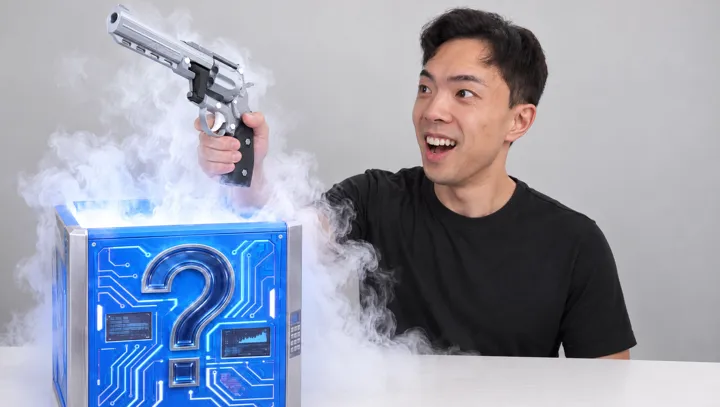
judges 6.6/10 · face 0.80
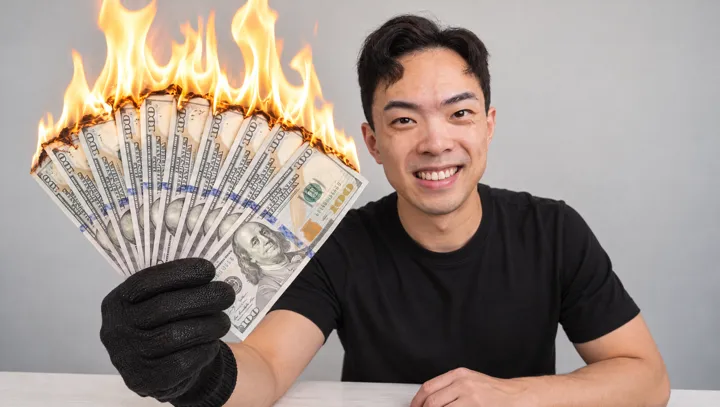
judges 7.0/10 · face 0.82
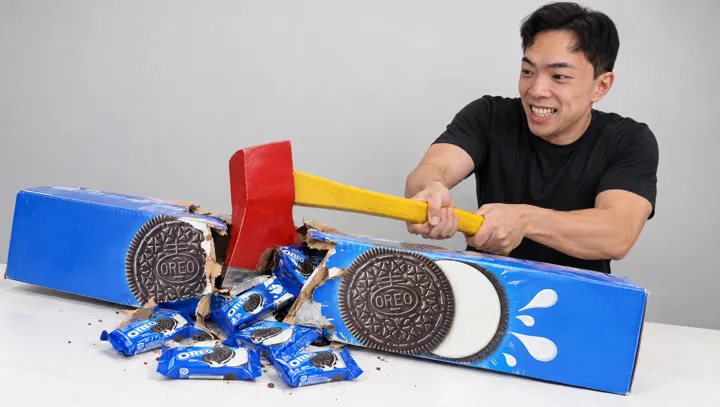
judges 6.4/10 · face 0.76
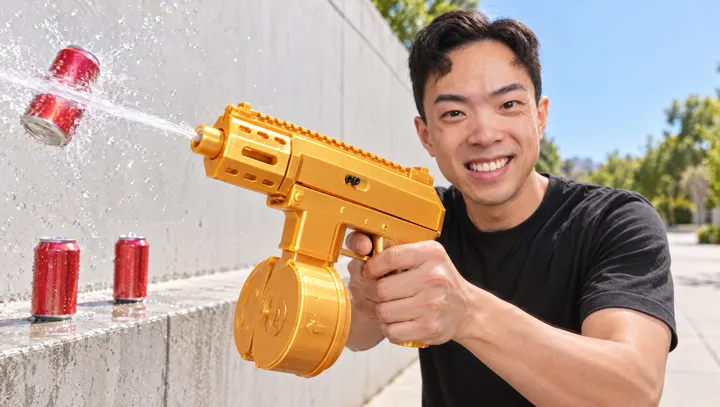
judges 7.1/10 · face 0.82
Later tests
A real outlier thumbnail as an extra reference Your picks: leaning yes, not proven
Your blind picks, 2 rounds on the same 23 ideas, 4 versions each (round 2 is the second set you pasted later; what it was is still to be confirmed with you). WIN plus one library thumbnail with the same layout was your most picked version both times: 18 of 43 picks (42%, where chance is 25%). A strong lean, not proof: both rounds share the ideas and the picker, and across the rounds you picked the same version for the same idea only 6 times in 20, so the versions are close. Using the library thumbnail INSTEAD of the round-5 style reference was picked least (6 of 43), so the round-5 style reference stays. After round 1 you said "just cuz i picked these doesn't mean i like them". Not added to the recipe.
GPT quality setting: low vs medium vs high Your call: always high
On your 5 approved A/B thumbnails: low kept the layout and face on 4 of 5 but lost texture and drifted on hard faces; medium was no clear middle; upscaling a low render did not bring the texture back. You: "i think high is better than low upscaled. let's keep at high". Side-by-side page
The new 3D plan (real pose + your head scan) Your call: not added
One concept, your upside-down drink sketch, 4 renders per version, blind AI judge. WIN + the new 3D plan vs WIN alone: matched your sketch 8 vs 6, natural body 8 vs 7, real-photo look 8 vs 6.5, same thumbnail score (7). The 3D colour plan scored highest (7.5). You: "i honestly don't think it's much better than studio v4", so it stays out. The -0.5 above was the old gray body model.
GTA 6 thumbnails: GPT vs Nano Banana 2 Split picks, GPT kept your face
Oct 30, first GTA round, 9 concepts, judged by my eye only (you did not judge it): GPT won 3, Nano Banana 2 won 3, 2 tied. GPT kept your face in the painted GTA style and added no stray text; Nano Banana 2 turned your face into a generic cartoon and invented text and logos ("CASE CLOSED", an R* logo, a Ferrari badge), though its rougher look read better for fan-made and in-game frames.
Running now: a real-proportions line In progress
Since Nov 5, 15% of renders are experiments (your call). First one: WIN plus an explicit "real body proportions" line, vs WIN. After 21 pairs: head size the same (0.705 vs 0.704), body check fails 7 vs 9, face match 0.758 vs 0.752. Your verdicts on them come with your next review. Queued next: your fixed favorite photo as the face reference, and softer outdoor daylight.
Other things the test found
- Face photo trap: 80 of your 182 expression photos are wide-eyed stares. Picking by face-match score picks the stares and GPT copies them. Natural photos are now hand-labelled.
- Fixing the face afterwards did not work: AI face re-edits lowered the match (0.68 to 0.65); pasting a real photo of your face raised the match on 4 of 5 but blanked the expression on all 6 checked, so it was reverted.
- GPT refuses about 1 idea in 10 (fire on people, real-looking guns, blades near faces). Those go to Nano Banana 2.1 with the same recipe; their faces are weaker (0.63).
- Idea sources: remixing your own past winning thumbnails gave the weakest ideas; the other 5 sources overlapped. Idea pickers: the data score (views behind the idea) predicted nothing, and checked against your own verdicts every picker was at chance.
What changed in the recipe since, from your reviews
- A STYLE block after "too realistic, not optimized for YouTube": strong colour contrast coming from the hero, the hero object the biggest thing in frame, a simple uncluttered background. Later toned to natural colour, "not oversaturated and not too perfect".
- Every GPT render at high quality (above).
- Face references are front photos only (the three-quarter photo is out), the "face large" wording is gone after "why do you make my head so big", and a face-lighting rule matches your face to the scene.
- Outdoor scenes get their own lighting (the indoor "even light, no shadows" wording made outdoor shots look fake).
- A body-proportion check after "head too big or body too big".
What none of this tested
- New photos of you: only the existing 182-photo library was used.
- Prompts written for Nano Banana or Seedream: they got the GPT prompt.
- Ideas the pickers threw away: only approved ideas were rendered.
- Your blind picks on the main test: the pick page was never filled in, so the main ranking is the judges' only.
Every render of every idea, per video: hafu-thumb-v4.pages.dev. Full write-up: work/in-development/thumbnail-system/v4/exp/REPORT.md.